Azure AI Solutions Architecture
Understanding LLMs
Large language models are the computational engines at the center of every modern enterprise AI system. This chapter dismantles their opacity: you will learn how tokens, context windows, and inference parameters translate directly into architectural decisions around latency, cost, and reliability, and how each known model limitation demands a specific mitigation pattern you must design in from the start.
Foundations of Large Language Model Architecture
How Transformer Models Process Language
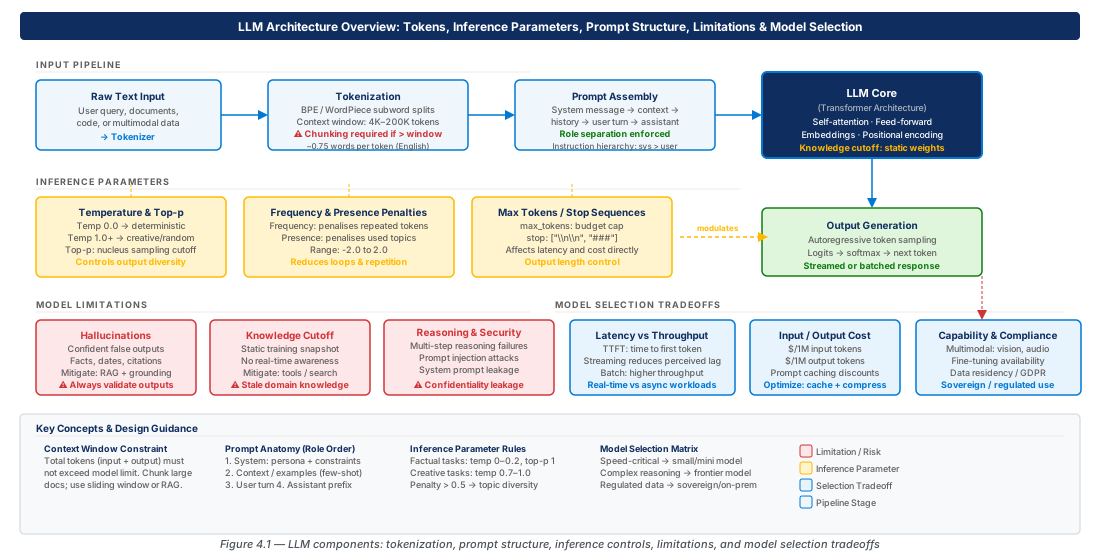
A large language model is a neural network trained to predict the next token given preceding tokens. The transformer architecture replaces recurrence with self-attention: each position attends to every other simultaneously, capturing long-range dependencies without vanishing-gradient problems. At inference time, the prefill phase processes the full prompt in parallel and builds a KV cache; the generation phase auto-regressively samples one token at a time, extending that cache.
This asymmetry explains why first-token latency and per-token latency behave differently and must be tuned separately. Model size in parameters is only one variable—context length, quantization precision, batch size, and hardware all interact with it to produce your actual latency, throughput, and cost envelope.
From Pre-training to Fine-tuning: The Model Lifecycle
Pre-training learns statistical patterns over hundreds of billions of tokens. Instruction fine-tuning (IFT) and RLHF then align the model to follow conversational roles—system, user, assistant. Violating that role structure in your prompt design degrades output quality in ways that are difficult to diagnose.
Domain-specific fine-tuning shifts the model's behavior distribution toward a narrower target domain, reducing prompt length and per-call token cost, but it does not update factual knowledge—that requires RAG.
Note
Fine-tuning and RAG are complementary, not competing. Fine-tuning shifts style and format; RAG injects current facts. Production systems typically need both.
Tokens and Tokenization: Architecture Implications
What a Token Is and How Tokenizers Work
A token is the fundamental unit an LLM processes. Byte-pair encoding (BPE) splits text into sub-word units: English prose averages ~0.75 tokens per word, but code, JSON/XML, and CJK text tokenize significantly more expensively. Architects must account for these ratios when estimating cost and designing RAG chunking strategies.
Profile your corpus with tiktoken before committing to an architecture. A 20% underestimate in token density can push chunks over embedding model input limits, silently truncating documents.
CE-07a — Estimate Token Counts for a Sample Corpus
RESOURCE_GROUP="rg-understanding-llms-architecture-dev-001"
STORAGE_ACCOUNT="stllmarchdev001eastus2"
az group create --name "$RESOURCE_GROUP" --location eastus2 --tags environment=dev chapter=ch04
az storage account create --name "$STORAGE_ACCOUNT" --resource-group "$RESOURCE_GROUP" \
  --sku Standard_LRS --min-tls-version TLS1_2 --allow-blob-public-access false
az storage blob upload-batch --account-name "$STORAGE_ACCOUNT" \
  --destination sample-corpus --source "./sample-docs/" --auth-mode login
echo "Corpus uploaded. Run token profiling function to measure tokenization ratios."
Context Windows: Constraints and Chunking Strategy
The context window is the sum of prompt tokens and completion tokens in a single call. Larger windows increase cost linearly with input tokens, add prefill latency, and can trigger "lost in the middle" attention degradation for mid-document content. These constraints drive RAG chunking strategy: fixed-size, semantic, or hierarchical.
Warning
Never design your chunking strategy assuming a fixed character-to-token ratio. Measure actual tokenization on your specific corpus. A 20% underestimate can silently truncate documents at embedding time.
CE-07b — Deploy Azure AI Search with Semantic Chunking
SEARCH_SERVICE="understanding-llms-prod-eastus2-001"
az search service create --name "$SEARCH_SERVICE" --resource-group "$RESOURCE_GROUP" \
  --sku Standard --replica-count 2 --partition-count 1
# Create data source pointing to document storage, then configure chunking indexer
echo "AI Search configured. Validate 95th-pct chunk ≤ 1500 tokens with 150-token overlap."
Context Budget Management in Multi-Turn Systems
Every conversation turn adds tokens; without active management the context window overflows. A context management layer maintains a sliding window, compresses older turns via a cheaper model, and tracks usage against a configurable budget that reserves space for the completion. For a 128K window a typical allocation is: 4K system message, 80K conversation history, 20K RAG context, 24K completion.
Azure API Management (APIM) policies can implement token counting and budget enforcement as a cross-cutting gateway concern, routing long-context requests to large-window models and short requests to lower-cost deployments.
Inference Parameters: Behavioral Control for Architects
Temperature, Top-p, and Sampling Strategy
Temperature scales the logit vector before softmax. Temperature 0 produces deterministic output; 1.0 samples the native distribution; values above 1.0 increase randomness. Use 0.0–0.3 for factual retrieval, code generation, and structured extraction; 0.7–1.0 for creative tasks. Temperature must be a per-use-case configuration parameter injected at the application layer, never a system-wide constant.
Top-p restricts sampling to tokens whose cumulative probability exceeds threshold p, pruning low-probability tail tokens. Tune either temperature or top-p, not both—their interactions are non-linear.
Tip
For any task feeding LLM output into a downstream structured pipeline (JSON parsing, database write, workflow trigger), set temperature to 0 and use Structured Outputs mode in Azure OpenAI Service to enforce grammar-constrained generation and eliminate JSON parse failures entirely.
Frequency and Presence Penalties
Frequency penalty reduces a token's logit proportionally to its prior occurrence count—use 0.1–0.5 for long-form generation to suppress repetition loops without degrading factual accuracy. Presence penalty applies a flat penalty to any token seen at least once, promoting thematic diversity in creative tasks. Both should be validated empirically on your specific workload.
Max tokens is a hard cost ceiling per call and an interaction surface for chain-of-thought tasks—set it generously for expected output length but bounded against runaway generation, with monitoring alerts when responses approach the limit.
CE-08a — Deploy Azure OpenAI with Per-Deployment Parameter Defaults
OPENAI_ACCOUNT="understanding-llms-prod-eastus2-001"
az cognitiveservices account create --name "$OPENAI_ACCOUNT" --kind OpenAI \
  --sku S0 --location eastus2 --resource-group "$RESOURCE_GROUP"
az cognitiveservices account deployment create --name "$OPENAI_ACCOUNT" \
  --deployment-name gpt-4o-prod --model-name gpt-4o --model-version "2024-11-20" \
  --model-format OpenAI --sku-capacity 100 --sku-name GlobalStandard
az cognitiveservices account deployment create --name "$OPENAI_ACCOUNT" \
  --deployment-name gpt-4o-mini-prod --model-name gpt-4o-mini --sku-capacity 200
System and User Message Structure: Prompt Architecture
The Role Hierarchy: System, User, and Assistant
Azure OpenAI uses a structured message format where each message carries a role: system, user, or assistant. The system message is processed first and has higher authority—it establishes persona, constraints, and output format. This hierarchy is the basis for prompt injection resistance, though no prompt-only defense is absolute.
Treat the system message as a first-class software artifact: version-controlled, reviewed, tested against a regression suite, and deployed through the same pipeline as application code.
Warning
Embedding user-supplied data directly in the system message without sanitization is one of the most dangerous patterns in LLM development. If an attacker can control any portion of the system message, they can override safety instructions. Always treat system message content as a code artifact, never as a user-configurable field.
Prompt Anatomy: Instructions, Context, Examples, Output Spec
A well-structured prompt has four logical zones in order: (1) instructions, (2) context, (3) examples, (4) output specification. Instructions first ensures the model reads task requirements before domain content dominates its representation. Examples after context gives the model background to interpret demonstrations. Output spec last reinforces format compliance at the moment of generation.
Dynamic few-shot selection—retrieving the most semantically similar (query, answer) pairs from a curated example store—consistently outperforms static examples on production workloads with high query variance, at the cost of additional latency and token spend.
CE-08b — Prompt Version Management via Azure App Configuration
APP_CONFIG="appconfig-llm-prompts-prod-eastus2-001"
az appconfig create --name "$APP_CONFIG" --sku Standard --location eastus2
az appconfig kv set --name "$APP_CONFIG" --key "prompts:system:enterprise-kb:v1" \
  --value "You are an expert enterprise knowledge assistant. Answer only from provided context." \
  --label prod --yes
az appconfig feature set --name "$APP_CONFIG" --feature prompt-v2-rollout --label prod --yes
# Add Microsoft.Targeting filter at 10% rollout for A/B test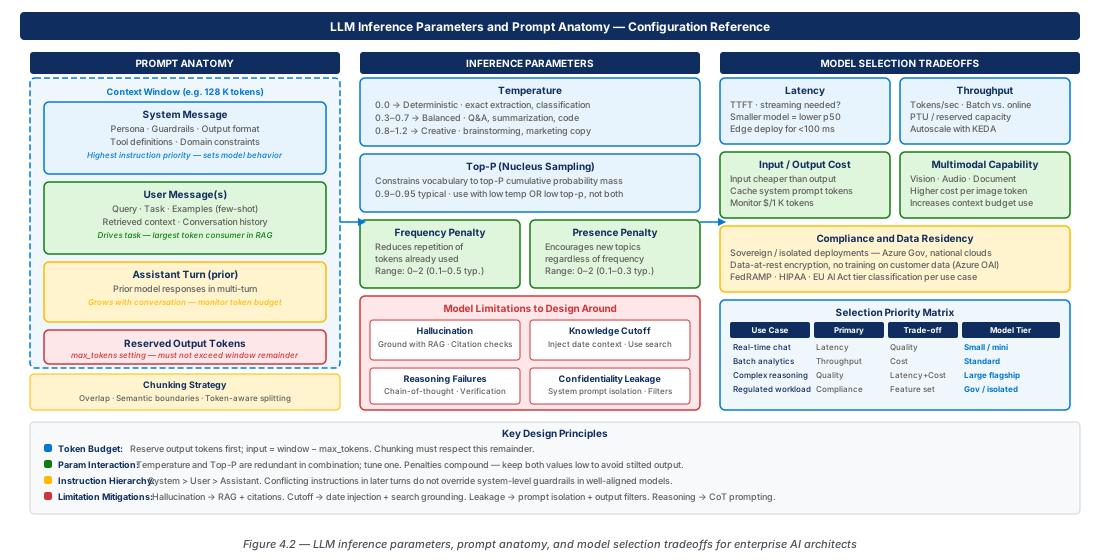
Model Limitations: Design Mitigations for Known Failures
Hallucination: Causes, Detection, and Mitigation Architecture
Hallucination is an intrinsic property of probabilistic generative models—no current LLM produces zero hallucinations across all inputs. The architectural response is a defense-in-depth stack: (1) constrained generation instructing the model to answer only from context, (2) source citation enforcement with post-processing verification, (3) output validation via a secondary model or rule-based validator, (4) human-in-the-loop checkpointing for high-stakes outputs.
Note
RAG significantly reduces factual hallucination but does not eliminate it. The model can still misread retrieved context or combine chunks incorrectly. Always show retrieved sources to end users alongside the answer to enable user-level verification.
Knowledge Cutoff: Temporal Blindness and Mitigation Patterns
Every LLM has a training data cutoff. The standard mitigation is RAG with a real-time or near-real-time ingestion pipeline: crawl authoritative sources, chunk and embed new content, and upsert vectors into Azure AI Search to keep the knowledge base current within hours for public information; use SharePoint/Confluence webhooks for internal content.
Always include the current date and the model's cutoff date in the system message. Without this, the model extrapolates from pre-cutoff trends—a subtler and harder-to-detect form of hallucination.
Reasoning Failures and Confidentiality Leakage
Reasoning failures—incorrect arithmetic, invalid inferences, multi-step ordering errors—compound in agentic workflows before a human reviews the output. Mitigate with chain-of-thought prompting and per-step checkpointing using Azure Durable Functions as the orchestration substrate.
For confidentiality leakage, use explicit system message refusal instructions, content filter prompt-injection shields, and Azure AI Search per-user filters to scope retrieval to authorized documents at the retrieval layer rather than relying on model self-censorship.
CE-08c — Configure Azure AI Content Safety for Output Validation
CONTENT_SAFETY_ACCOUNT="cs-llm-arch-prod-eastus2-001"
az cognitiveservices account create --name "$CONTENT_SAFETY_ACCOUNT" \
  --kind ContentSafety --sku S0 --location eastus2 \
  --resource-group "$RESOURCE_GROUP" --tags environment=prod chapter=ch04
# Create custom blocklist for system prompt disclosure patterns via REST API
echo "Integrate with APIM to filter all LLM responses before returning to clients."
Model Selection: Architectural Tradeoffs
Capability, Cost, and Latency Matrix
Selecting the right model is a multi-dimensional optimization—no model is strictly superior on all dimensions. The table below summarizes primary tradeoffs across Azure OpenAI Service model tiers as of mid-2026. Always validate against the Azure pricing calculator before finalizing decisions.
| Model | Context | Input ($/1M) | Output ($/1M) | P50 First Token | Multimodal | Best Fit |
|---|---|---|---|---|---|---|
| GPT-4o | 128K | $2.50 | $10.00 | 800–1,200ms | Vision, audio | Complex reasoning, multi-step agents, vision |
| GPT-4o mini | 128K | $0.15 | $0.60 | 400–700ms | Vision | High-volume extraction, classification, RAG synthesis |
| o3 | 200K | $10.00 | $40.00 | 5–30s | Vision | Math reasoning, code verification, complex planning |
| o4-mini | 200K | $1.10 | $4.40 | 2–10s | Vision | Cost-efficient deep reasoning, STEM tasks |
| text-embedding-3-large | N/A | $0.13 | N/A | 50–150ms | None | High-quality semantic embeddings for RAG |
| text-embedding-3-small | N/A | $0.02 | N/A | 30–80ms | None | Cost-sensitive embedding at scale |
Note
Thinking models (o3, o4-mini) produce dramatically better results on complex reasoning tasks but make first-token latency unsuitable for real-time user-facing interactions. Restrict them to batch, asynchronous, or expert-review workflows where quality improvement justifies the latency.
Compliance and Residency Considerations
Enterprise model selection cannot be driven by capability and cost alone. Azure OpenAI Service provides data processing commitments including no training on customer data by default, regional data residency, and coverage under EU Data Boundary, HIPAA BAA, and FedRAMP frameworks. These commitments apply to Azure OpenAI Service specifically—verify terms for every model component in your architecture including embedding models and rerankers.
For HIPAA, FedRAMP High, or IL4/IL5 workloads, Azure Government regions offer certified model subsets with a 3–6 month availability lag versus commercial regions. Design fallback patterns for cases where a required model version has not yet been certified in your compliance boundary.
CE-08d — Deploy Azure OpenAI with Private Networking for Compliance
PE_NAME="pe-openai-prod-eastus2-001"
az cognitiveservices account update --name "$OPENAI_ACCOUNT" \
  --resource-group "$RESOURCE_GROUP" --public-network-access Disabled
az network private-endpoint create --name "$PE_NAME" \
  --vnet-name "vnet-llm-arch-prod-eastus2-001" --subnet "snet-openai-pe-prod-001" \
  --group-id account --resource-group "$RESOURCE_GROUP"
az network private-dns zone create --name "privatelink.openai.azure.com" \
  --resource-group "$RESOURCE_GROUP"
echo "All traffic to Azure OpenAI now flows through VNet without traversing public internet."
Lab
CE-07 — Profile Token Density and Design Chunk Strategy
Provision dev resources, upload a sample corpus to blob storage, and validate token density before finalizing chunk size. Use the tokenization endpoint output to set CHUNK_SIZE_TOKENS so the 95th-percentile chunk stays at or below 1,500 tokens with 150-token overlap.
set -euo pipefail
RESOURCE_GROUP="rg-understanding-llms-architecture-dev-001"
az group create --name "$RESOURCE_GROUP" --location eastus2 --tags chapter=ch04-lab
az storage account create --name "stllmarchdev$(echo $RANDOM | cut -c1-4)" \
  --resource-group "$RESOURCE_GROUP" --sku Standard_LRS --allow-blob-public-access false
az storage blob upload-batch --destination sample-corpus --source "./sample-docs/" --auth-mode login
az search service create --name "srch-llm-arch-dev-eastus2-001" \
  --resource-group "$RESOURCE_GROUP" --sku Basic
echo "Validate token density and adjust CHUNK_SIZE_TOKENS before promoting to prod."CE-08 — Instrument Azure OpenAI for Cost, Latency, and Token Monitoring
Deploy a Log Analytics workspace, enable diagnostic settings for RequestResponse and Audit logs, create metric alerts for token quota at 85% TPM and P99 latency at 10s. All resources tagged for cost attribution.
LAW_NAME="law-llm-arch-prod-eastus2-001"
LAW_ID=$(az monitor log-analytics workspace create --workspace-name "$LAW_NAME" \
  --resource-group "$RESOURCE_GROUP" --retention-time 90 --query id -o tsv)
az monitor diagnostic-settings create --name diag-openai-to-law-prod \
  --resource "$OPENAI_ID" --workspace "$LAW_ID" \
  --logs '[{"category":"RequestResponse","enabled":true},{"category":"Audit","enabled":true}]'
az monitor metrics alert create --name alert-openai-token-quota-prod \
  --condition "avg TokenTransaction > 85000" --window-size 5m --severity 2
echo "Observability stack deployed. Monitor token quota and P99 latency dashboards."
Summary
| Concept | Key Architectural Takeaway |
|---|---|
| Transformer phases | Prefill and generation have different latency profiles; tune first-token and per-token latency separately. |
| Tokenization | Profile your corpus with tiktoken before sizing. Code, CJK, and JSON tokenize more expensively than English prose. |
| Context budget | Allocate the window explicitly across system message, history, RAG context, and completion reserve. |
| Inference parameters | Temperature is per-use-case, not system-wide; use structured outputs mode for JSON-dependent pipelines. |
| Prompt architecture | Version system messages as code; order zones as instructions → context → examples → output spec. |
| Hallucination | Defense-in-depth: constrained generation + citation enforcement + output validation + human checkpointing. |
| Model selection | Optimize across capability, cost, latency, context, multimodal, and compliance; reserve thinking models for async workflows. |
Chapter: 4 of 12 | Status: v0.1 Draft |