Azure AI Solutions Architecture: Designing and Operating Enterprise AI Systems
Advanced RAG Patterns
Naive retrieval-augmented generation — embedding a query, fetching top-k chunks, and stuffing them into a prompt — works in demos but collapses under real enterprise workloads. This chapter maps the full library of advanced RAG patterns on Azure: query rewriting and decomposition, graph-augmented retrieval, agentic tool use, multimodal understanding, and conversational continuity, giving architects the decision criteria to match the right pattern to each workload's document type, query complexity, and latency budget.
1. Foundations: Why Naive RAG Fails at Enterprise Scale
The Retrieval-Quality Gap
Enterprise knowledge bases are rarely uniform. A single Azure AI Search index may hold structured financial tables, long-form policy PDFs, API reference docs, and informal Teams exports. Naive RAG applies a single embedding model and a single top-k threshold to all of them — retrieval that is simultaneously too broad and too narrow. The gap is compounded by query vocabulary: enterprise users phrase questions in their business domain language, not the document language, and hybrid BM25+dense retrieval narrows but does not close the lexical distance.
A third failure mode is context fragmentation: 512-token chunk boundaries often cut through paragraphs that derive meaning from adjacent text. Advanced chunking strategies — parent-child, hierarchical, sentence-window — exist specifically to solve this, and are addressed in depth later in this chapter.
The Production Architecture Mindset
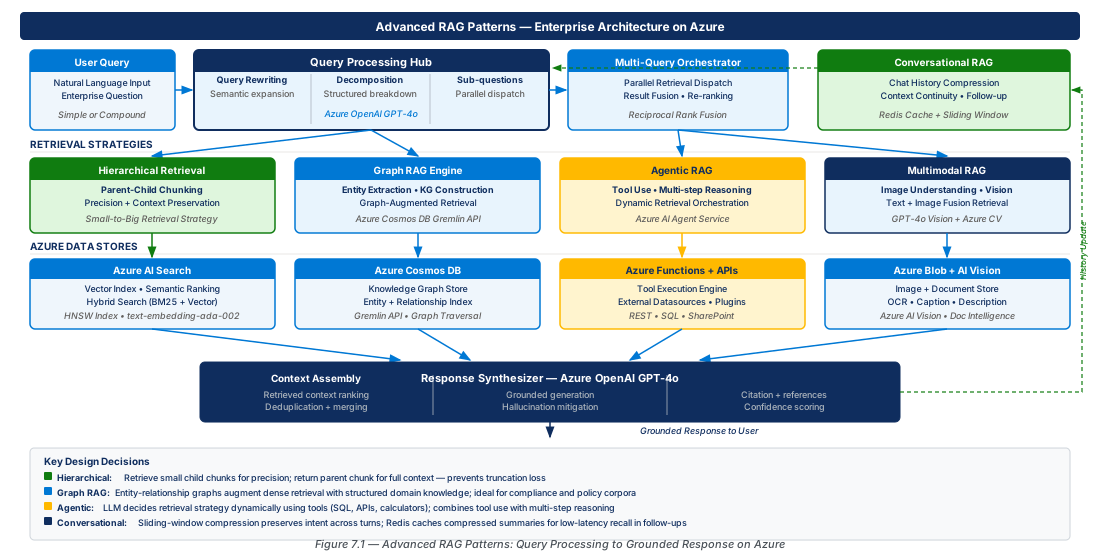
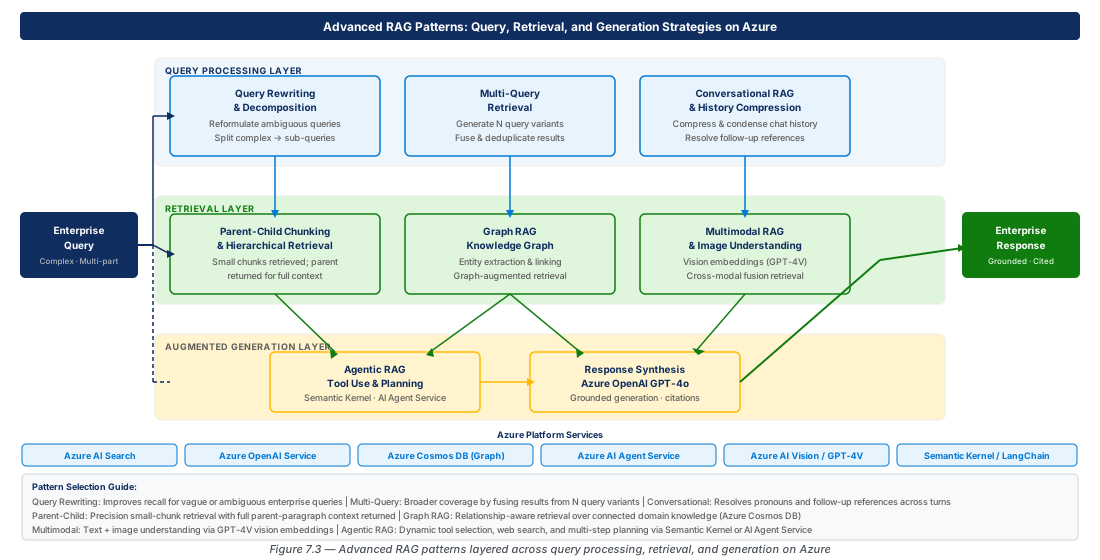
Each pattern in this chapter is a transformation applied at one of three stages: the query stage, the retrieval stage, or the generation stage. Patterns compose: a production system will typically combine query decomposition with parent-child chunking and citation-grounded generation. Latency budgets must be a first-class design input — a pipeline that rewrites, decomposes, multi-query retrieves, re-ranks, and generates can accumulate 8–15 seconds of end-to-end latency. For interactive chat that is unacceptable; for an asynchronous research assistant it is entirely reasonable.
2. Query Transformation: Rewriting, Decomposition, and Multi-Query Retrieval
Query Rewriting for Vocabulary Alignment
Query rewriting uses a language model (typically GPT-4o-mini in Prompt Flow or a custom Azure Function) to reformulate the user's question before embedding — expanding domain synonyms, normalising phrasing, and removing noise words. Sophisticated implementations generate three to five rewrites, embed each independently, query in parallel, merge via document-ID deduplication, and re-rank before context assembly. The cost is negligible relative to the downstream GPT-4o generation call.
Tip
Use a focused system prompt: "Rewrite the following question to maximise recall against a corpus of enterprise contracts. Preserve intent. Output only the rewritten question." Instrument rewrites with Application Insights custom events logging the original query, each variant, and the resulting hit list.
Query Decomposition for Multi-Hop Reasoning
Decomposition breaks compound questions into an ordered sequence of simpler sub-questions, each answerable by a single retrieval step, with results from earlier steps injected as context for later ones. This underlies LlamaIndex Sub-Question Query Engine and LangChain multi-step agents, both deployable on Azure AI Foundry or Azure Kubernetes Service. Azure Durable Functions is a natural fit: each sub-question becomes an activity function, independent branches execute in parallel, and a fan-in activity aggregates the final answer.
Warning
Decomposition multiplies LLM calls per user request. A five-sub-question query with three retrieval steps each produces 15+ round trips. Model cost-per-query carefully and enforce per-request token budgets in your orchestration layer.
Multi-Query Retrieval and Reciprocal Rank Fusion
Multi-query retrieval generates N variant phrasings, executes each as an independent vector search, and merges using Reciprocal Rank Fusion: score = ∑(1/(rank+60)) across queries, sort by combined score. RRF is the fusion algorithm built into Azure AI Search hybrid retrieval mode. A four-variant strategy (formal terminology, colloquial phrasing, entity-focused, predicate-focused) provides meaningful improvement over single-query retrieval at ~4x vector search overhead — typically sub-200ms per query on an S2-tier index.
3. Parent-Child Chunking and Hierarchical Retrieval
The Chunking Dilemma
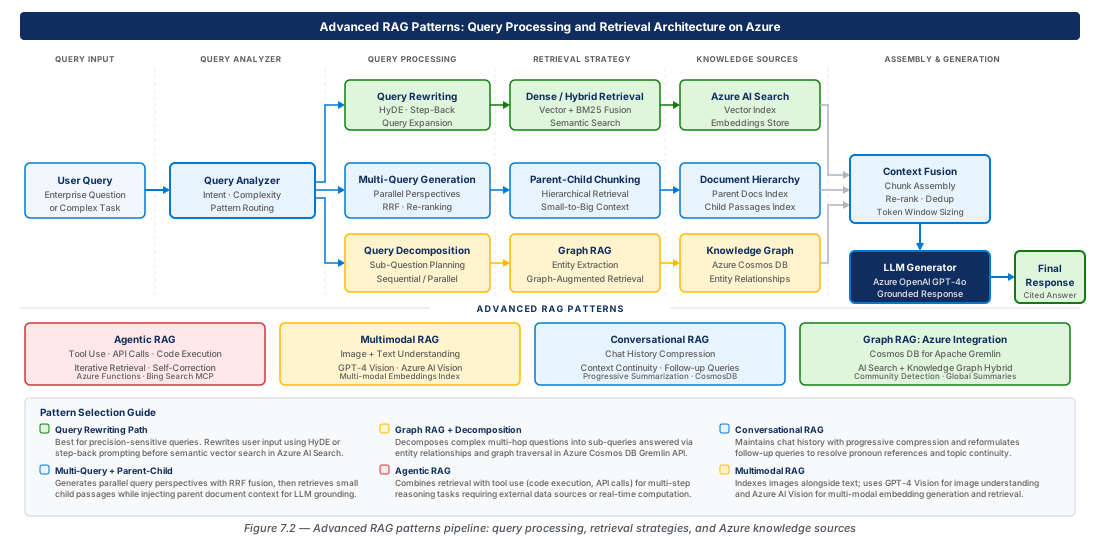
Small chunks (128–256 tokens) produce precise embeddings but lose surrounding context; large chunks (1024–2048 tokens) preserve context but dilute embedding precision. Parent-child chunking resolves this by decoupling retrieval unit (the small, precisely-embedded child chunk) from context delivery unit (the larger, semantically-complete parent chunk). In Azure AI Search, both are indexed as separate documents sharing a parentId field; retrieval searches child embeddings then fetches parent content via a secondary Documents-Get lookup (~5–20ms overhead).
Hierarchical Retrieval and Sentence-Window Techniques
Hierarchical retrieval generalises this to an arbitrary tree: document → section → paragraph → sentence. Retrieval starts at the finest granularity for precision, then expands upward until the token target window is filled. The sentence-window variant embeds individual sentences but retrieves a configurable window of surrounding sentences (e.g., ±3 sentences), implemented in Azure AI Search via sentence offset and document ID metadata with a range filter query.
Note
A document indexed at three granularity levels occupies approximately 2.5–3x the storage of a single-level index. Factor this into Azure AI Search tier selection for corpora exceeding 100 GB.
Overlap, Sliding Windows, and Late Chunking
Overlap chunking shares 10–20% of tokens across adjacent chunks to mitigate boundary fragmentation, but increases index storage and embedding costs proportionally. Late chunking — supported by JinaAI models in the Azure AI Foundry catalogue — passes the entire document through the embedding model and extracts per-token embeddings post-hoc, giving chunk embeddings full-document context at index time. This is compelling for cross-reference-dense corpora (legal codices, technical standards) but adds embedding-time latency.
Tip
Start with parent-child chunking using 512-token child chunks and 1500-token parent chunks. Add hierarchical retrieval or late chunking only after offline evaluation shows the simpler approach is insufficient for your quality targets.
4. Graph RAG: Knowledge Graph Construction and Graph-Augmented Retrieval
Why Vector Search Alone Cannot Model Entity Relationships
Vector similarity is a nearest-neighbour problem — excellent at semantic similarity but with no native representation of structured relationships. A question like "which suppliers have both an active ISO 9001 certification and a pending regulatory action?" requires joining two semantically-independent relationship types that no single query embedding can bridge. Graph RAG constructs a knowledge graph alongside the vector index: entities are extracted with an LLM-based NER step, relationships via relation extraction, and triples stored in Azure Cosmos DB for NoSQL or a Neo4j instance on Azure Kubernetes Service (AKS).
Microsoft's open-source GraphRAG framework automates community-level summary construction from large corpora using GPT-4-class models for entity/relationship extraction, Leiden algorithm for community detection, and multi-level summaries enabling both local (specific entity) and global (theme-level) query modes.
Entity Extraction and Knowledge Graph Construction on Azure
The production pipeline has four stages: document ingestion via Azure AI Document Intelligence, LLM-based entity and relationship extraction to Azure OpenAI outputting validated JSON, graph construction with entity deduplication using embedding-based similarity clustering, and community detection with summary generation. Deduplication ("Microsoft Corporation" vs "MSFT") uses string normalisation plus a configurable confidence threshold above which entities are merged. Incremental operation is mandatory — enterprise corpora change continuously.
Warning
LLM-based extraction of a 10,000-document corpus using GPT-4o can cost several hundred dollars. Profile extraction prompts carefully, cache results for unchanged documents, and use a two-tier approach (GPT-4o-mini for initial extraction, GPT-4o only for low-confidence entities).
Graph-Augmented Retrieval Patterns
Three patterns compose on the knowledge graph. Entity-centric retrieval identifies query entities via NER, looks them up in the graph, retrieves their neighbourhood, and combines structured facts with vector-retrieved chunks — ideal for "What are all subsidiaries of Contoso with active SLAs?" Community-based global query selects community summaries from the graph hierarchy as primary generation context — ideal for "What are the most significant regulatory risks across our vendor portfolio?" Hybrid graph-vector runs both in parallel and fuses before generation, providing maximum quality at maximum architectural complexity.
Important
Graph RAG requires an event-driven update pipeline triggered by document changes. Plan for graph maintenance operations in your runbook: entity deduplication drift correction, community re-detection after large corpus updates, and Cosmos DB backup/restore procedures.
5. Agentic RAG: Combining Retrieval with Tool Use
From Static Retrieval to Dynamic Tool Orchestration
Agentic RAG gives the LLM the ability to decide what to retrieve, when to retrieve it, and when to call non-retrieval tools (calculators, code interpreters, API clients). The model operates in a ReAct-style loop: reason → action (tool call) → observe → iterate. On Azure, this is implemented on Azure AI Agents Service (GA early 2026) with built-in tool registration, state management, and audit logging via Application Insights.
The key design decision is tool granularity. A single monolithic "search" tool is simplest but limits retrieval intent. A richer set — separate tools for document type, date range, entity name, and metadata filters — enables targeted calls but increases tool-selection prompt complexity and hallucination risk. Empirically, 5–8 well-described tools with clear parameter schemas outperforms both extremes.
Multi-Agent RAG Architectures
A router agent examines incoming questions and routes them to specialist agents (contracts, financial, compliance), each with its own index and tools. On Azure AI Agents Service, specialist agents are themselves agent instances registered as tool calls on the parent agent, forming a hierarchical tree observable as a unified execution graph in Azure AI Foundry's tracing UI — surfacing bottlenecks and routing errors.
Tip
Design each specialist agent to be independently testable with a well-defined input schema and golden-answer test cases. Use Azure AI Evaluation's batch evaluation feature to run these tests in CI/CD pipelines before integration.
Agentic RAG with Code Interpretation and External APIs
Azure OpenAI's code interpreter provides a sandboxed Python runtime (pandas, numpy, matplotlib) enabling the agent to retrieve documents, extract structured data, and perform numerical analysis in a single loop. External APIs (SAP Ariba, Dun & Bradstreet, internal Azure Data Factory pipelines) are registered as OpenAPI-described function tools, with credentials in Azure Key Vault and Managed Identity for Microsoft Entra ID-enabled services.
Warning
Enforce per-tool call budgets (max calls per agent turn), 10-second timeout thresholds, and circuit-breaker logic via Azure API Management policies. A looping agent calling external APIs can exhaust quotas and generate unexpected costs within seconds.
6. Multimodal RAG: Retrieval with Image Understanding
Extending RAG to Visual Content
Engineering CAD diagrams, financial charts, product photographs, and medical images all carry information not present in surrounding prose. Multimodal RAG leverages GPT-4o/GPT-4o-mini via Azure OpenAI to generate rich textual descriptions of images at index time. These descriptions are embedded and indexed alongside text in Azure AI Search. At retrieval time, the system can retrieve both text chunks and image descriptions, and the generation step can include the original image in a multimodal prompt for direct visual grounding.
Azure AI Document Intelligence provides foundational image/table extraction with bounding box coordinates, available as a built-in skill in Azure AI Search integrated vectorization — reducing custom code for the multimodal indexing pipeline.
Indexing and Retrieving Visual Content
The pipeline has two parallel tracks. The text track follows standard RAG chunking. The image track extracts figures and tables via Azure AI Document Intelligence, generates descriptions via GPT-4o with structured prompts (chart type, axis labels, data trends; component names and flow directions for diagrams), and embeds using the same model as the text track — both writing to the same index with a contentType field. For tables, generate a natural-language summary via GPT-4o-mini and embed the summary, storing the raw Markdown table as a non-indexed retrieval field.
Note
Multimodal indexing with GPT-4o image descriptions significantly increases indexing cost. For text-dominant documents with occasional diagrams, use on-demand description at query time rather than pre-indexing all images — trading per-query latency for lower indexing cost.
Multimodal Generation and Visual Grounding
Include the original image alongside its description in the multimodal prompt for visual grounding — the model can read exact values from charts rather than relying on approximate values in auto-generated descriptions. Store the image's Azure Blob Storage URL alongside its embedded description in Azure AI Search and propagate it through retrieval and assembly to the final response, enabling visual citations (thumbnail or link) in the UI.
| Retrieval Approach | Image Handling | Best For | Azure Services |
|---|---|---|---|
| Text-only RAG | Ignored | Text-dense corpora, few images | Azure AI Search, Azure OpenAI |
| Image description indexing | Descriptions pre-generated | Large image-rich corpora | AI Document Intelligence, Azure OpenAI, Azure AI Search |
| On-demand image description | Descriptions at query time | Small corpora, low indexing budget | AI Document Intelligence, Azure OpenAI |
| Full multimodal RAG | Description indexing + image in generation | Maximum quality for visual content | All above + GPT-4o multimodal |
7. Conversational RAG: Chat History and Context Continuity
The Stateful Retrieval Problem
Standard RAG is stateless — each query processed independently. Enterprise conversational AI (HR self-service, procurement bots, IT helpdesk agents) requires follow-up questions that are elliptical, pronoun-referential, or topic-extending. A system retrieving against the bare follow-up question almost always returns irrelevant results. Conversational RAG adds a query contextualisation step: "Given the conversation history, rewrite the latest message as a standalone question answerable without prior context." The rewritten question drives retrieval.
Chat History Compression Strategies
Fixed-window truncation retains the last N turns (typically 5–10, ~1,000–3,000 tokens) — simple and effective when recent context dominates. Progressive summarisation maintains a running summary of key entities, document scopes, confirmed facts, and open questions alongside the recent window, preserving long-range context at bounded token cost. Entity-aware compression builds a per-entity context graph across the conversation and selects turns dynamically based on entity overlap with the current query — powerful for complex multi-entity enterprise conversations.
Tip
Start with fixed-window truncation (last 6 turns) combined with a system-prompt entity scratchpad where the model maintains a running list of key entities and constraints. This provides most of the benefit of progressive summarisation at a fraction of the implementation complexity.
Context Continuity and Follow-Up Query Handling
A lightweight classification step using GPT-4o-mini (~200–400ms) categorises each message as new-question, follow-up, clarification-request, scope-change, or correction, routing each to the appropriate handler. Scope changes update a session-level filter state stored in Azure Cosmos DB (partition key: Entra ID subject claim, TTL: 86400s) that persists across turns. Correction requests trigger targeted retrieval with additional constraints. Session state — history, summary, entity scratchpad, filter state, citation history — reads at <5ms P99 for documents under 4KB.
Important
Conversational RAG introduces a persistent prompt-injection attack surface. Validate all retrieved text before including it in the system prompt or history context. Enforce server-side control of filter state — never accept filter parameters from the client without server-side validation and authorisation checks.
8. Lab
CE-13: Deploy a Multi-Query RAG Pipeline with Parent-Child Chunking on Azure AI Search
This lab provisions Azure AI Search (S2) with a two-tier parent/child index schema, deploys Azure OpenAI with text-embedding-3-large, GPT-4o-mini, and GPT-4o, and wires up a Prompt Flow pipeline executing multi-query retrieval with RRF fusion. Outputs are the Search and OpenAI endpoints ready for orchestration integration.
RG="rg-advanced-rag-patterns-prod-001"
SEARCH="advanced-rag-prod-eastus2-001"
AOAI="aoai-advanced-rag-prod-eastus2-001"
az group create --name $RG --location eastus2
az search service create --name $SEARCH --resource-group $RG --sku S2 --replica-count 2 --partition-count 2
az cognitiveservices account create --name $AOAI --resource-group $RG --kind OpenAI --sku S0 --location eastus2 --yes
# Deploy text-embedding-3-large (child chunks), gpt-4o-mini (rewriting), gpt-4o (generation)
az cognitiveservices account deployment create --name $AOAI --resource-group $RG --deployment-name text-embedding-3-large --model-name text-embedding-3-large --sku-capacity 120 --sku-name Standard
# Create parent-chunks index (no vector field) and child-chunks index (HNSW, 3072-dim)
# See chapter repo /scripts/ch07/create-indexes.sh for full index JSON schemas
echo "CE-13: Indexes ready for multi-query RAG pipeline"CE-14: Deploy Graph RAG with Azure Cosmos DB and Azure AI Agents Service
This lab provisions Azure Cosmos DB for NoSQL with containers for entities, relationships, community summaries, and conversational session state (TTL 86400s), creates an Azure Key Vault for secrets, deploys an AI Hub and Project, and establishes a managed identity with scoped RBAC roles for Key Vault and Azure AI Search.
RG="rg-advanced-rag-patterns-prod-001"
COSMOS="cosmos-advanced-rag-prod-eastus2-001"
az cosmosdb create --name $COSMOS --resource-group $RG --locations regionName=eastus2 failoverPriority=0 isZoneRedundant=true --default-consistency-level Session
az cosmosdb sql database create --account-name $COSMOS --resource-group $RG --name graphrag-db
# Containers: entities (/entityType), relationships (/sourceEntityType),
#             community-summaries (/level), sessions (/userId, ttl=86400)
az keyvault create --name kv-adv-rag-prod-eu2-001 --resource-group $RG --enable-rbac-authorization true
# Grant managed identity Key Vault Secrets User + Search Index Data Reader roles
echo "CE-14: Graph RAG infrastructure deployed"
9. Summary
| Pattern | Key Design Point | Primary Azure Services |
|---|---|---|
| Query Rewriting | Lightweight GPT-4o-mini call bridges vocabulary gap; instrument with Application Insights | Azure OpenAI, Prompt Flow |
| Query Decomposition | Azure Durable Functions parallelises independent sub-question branches | Azure OpenAI, Azure Durable Functions |
| Parent-Child Chunking | Embed child (512 tokens), return parent (1500 tokens) via parentId lookup | Azure AI Search |
| Graph RAG | Microsoft GraphRAG + entity extraction + Leiden community detection; plan for incremental updates | Azure OpenAI, Azure AI Search, Azure Cosmos DB |
| Agentic RAG | 5–8 well-described tools; circuit-breaker + per-call budgets enforced at API Management | Azure AI Agents Service, Azure API Management |
| Multimodal RAG | AI Document Intelligence extracts images; GPT-4o generates descriptions; propagate Blob URLs for visual citations | Azure AI Document Intelligence, Azure OpenAI, Azure AI Search |
| Conversational RAG | Contextualise queries before retrieval; manage session state in Cosmos DB with user-scoped partition keys and TTL | Azure OpenAI, Azure Cosmos DB, Azure AI Search |
Chapter: 7 of 12 | Status: Chapter draft v0.1 |